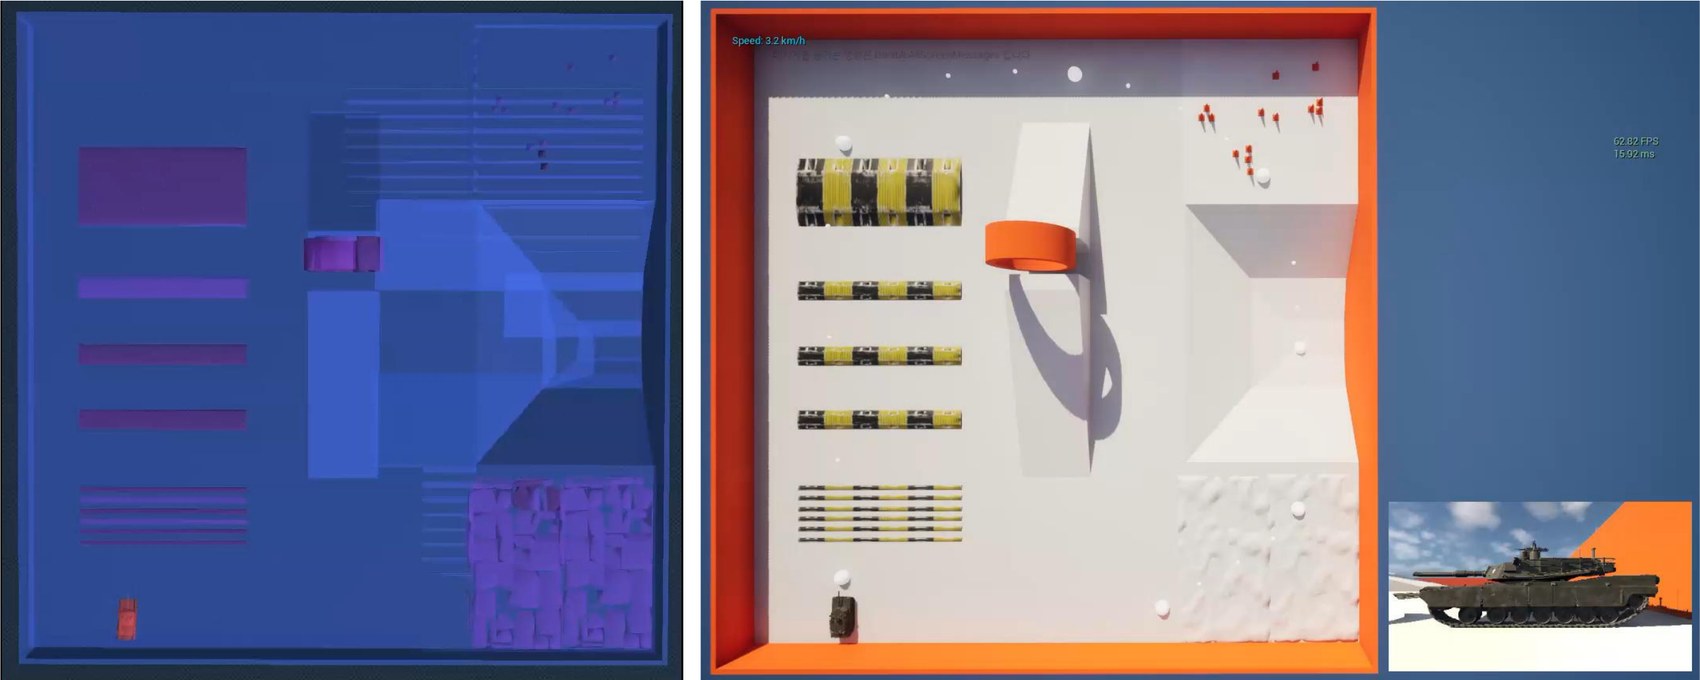
Real2Sim & Sim2Real — Aligning Dynamics Across Physics Systems
Two physics systems never agree. Record a vehicle following a path — in the real world, or in another simulator — then feed exactly the same steering and throttle into a different engine, and the vehicle will not follow the same path. Tire model, contact solver, integrator, mass distribution: every one of them differs, and the errors compound.
That disagreement is the core problem of this project. We work on aligning dynamics across different physics systems — recovering, for a target physics engine, the control inputs that make it reproduce an observed trajectory. This is what makes a simulator a usable stand-in for the real world, and it is the foundation everything else here is built on: without it, a policy trained in simulation is trained against the wrong physics.
Path2ST — converting a path into the target system’s controls
Our approach does not replay controls; it re-derives them. A reference trajectory is expressed in system-independent kinematic terms — curvature and acceleration along the path — and then converted into the steering and throttle that the target dynamic system needs in order to realize it. We call this Path2ST.
How the conversion is made fast and precise
The conversion has to run inside the control loop, which rules out solving it the expensive way. Differentiable inverse control — back-propagating through the simulator to find the control that produces the desired next state — is accurate but costs about 299 ms per step.
Instead we sweep the vehicle’s drive-train offline into a lookup table over speed and throttle against acceleration, invert that table at run time, and close the loop with a PD steering correction. Building the table takes 14 seconds, once. Control then costs 0.056 ms per step — roughly 5,300× less — and tracks at least as well: 0.044 m mean cross-track error against 0.078 m, with a maximum of 0.100 m. High-speed, precise control is what this combination buys, and it is what makes the aligned simulator usable in a closed loop rather than only offline.
Differentiable physics is kept for where precise simulation is actually required — offline system identification, and states the table never covered. A lookup table only spans the region it was swept over, and grows combinatorially with state dimension: 78K entries in four dimensions, 42M once steering angle, lateral velocity and yaw rate are added. Halve the vehicle’s mass mid-run and the tabulated controller leaves the path by 3.9 m, while the differentiable controller — re-solving the control at every step — holds it within 0.3 m. The two are complements rather than competitors: the table drives, and the differentiable solver identifies and rescues.
Building a control system inside the aligned world
Once the simulator’s dynamics are aligned to the target system, it becomes a place where a full control stack can be developed and evaluated rather than merely animated. That stack is the second half of this project:
- Physics-consistent path generation — reference trajectories the vehicle model can actually execute, with their optimal control pairs extracted through the sweep table and PD controller.
- Nominal tracking (Path2ST) — behavior-cloned steering with PID and feed-forward speed control, following the reference in real time.
- Residual reinforcement learning — a gated correction that stays inert while the nominal controller performs well, and compensates steering error only in out-of-distribution regimes such as hard braking or sharp turns.
- Deterministic safety shield — a STOP/PASS constraint imposed on the policy’s output when a crossing conflict is predicted.
The division of labour between the learned and the imposed parts is deliberate, and measurable. Across 660 safety-critical crossing scenarios, a residual policy alone tracks well (0.061 m) but fails 58.5% of the time; a rule-only shield is safe but destroys tracking (5.96 m, 10.0% failure). Composed, they give 1.5% failure at 0.090 m tracking error, and the remaining failures are physically unavoidable. Collision penalties in the reward were not sufficient to induce sustained yielding — the constraint has to be structural rather than learned.
Two further results shape how the stack is trained and recovered. Off-nominal recovery is handled by planning rather than by a learned policy — Frenet-quintic and Dubins candidates filtered by steering and braking feasibility, ranked by path length, merge distance, steering effort and speed loss, then merged back into the reference — which leaves the nominal stack untouched and stays inspectable when it fails. And generalization comes from environment diversity rather than episode length: training across 99 paths on multiple 3 km × 3 km terrains transfers to unseen environments better than long-horizon training on a single 500 m terrain (8.89 cm against 10.41 cm cross-track error), in about a third of the wall-clock time.
Where this is going — integration with a VLA planner
The direction of the project is to bring all of this under a vision-language-action (VLA) planner. The planner proposes a trajectory from camera observations, ego history and navigation intent; Path2ST converts that trajectory into controls the vehicle model can execute; the safety shield constrains what the policy is allowed to do when a crossing conflict is predicted; and the loop re-plans on each new observation.
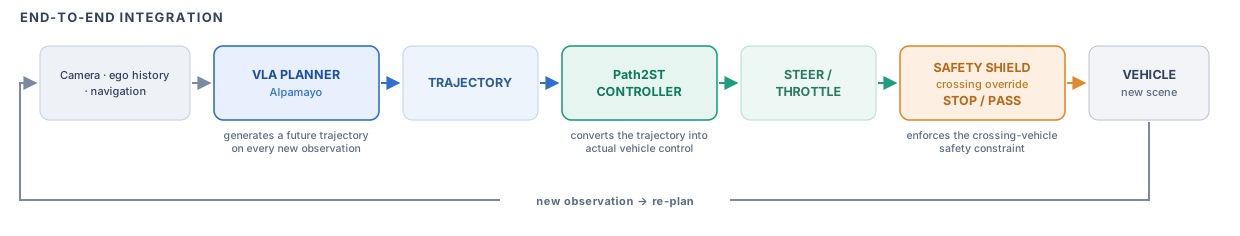
The separation of responsibilities is the point. The planner proposes, the controller tracks, and the shield enforces what must hold — so that a large learned model can supply intent and semantics without being trusted with the guarantees, which stay in explicit, verifiable components. Dynamics alignment is what makes that division safe to rely on: the controller and the shield reason about a physics that has been calibrated against the real system rather than an approximation of it.
programming experience
Python, PyTorch, Genesis, differentiable simulation, Isaac Lab, Blender, RL frameworks (PPO/QMIX), behavior cloning + residual RL, trajectory planning